Context Runtime
Executive Summary
The AI industry has spent the past two years building better language models, better retrieval systems and better agent frameworks.
Yet every production AI application still rebuilds the same infrastructure. Every engineering team writes custom code to decide:
- What information should reach the model?
- Which retrieval strategy should be used?
- Which model should execute the task?
- Should previous context be retrieved, compressed or discarded?
- Should another model verify the answer?
- Should work be delegated to multiple agents?
These decisions are currently embedded in application code. They should be infrastructure.
Context Runtime is a provider-agnostic optimization layer that automatically determines the optimal context execution plan before any model is called.
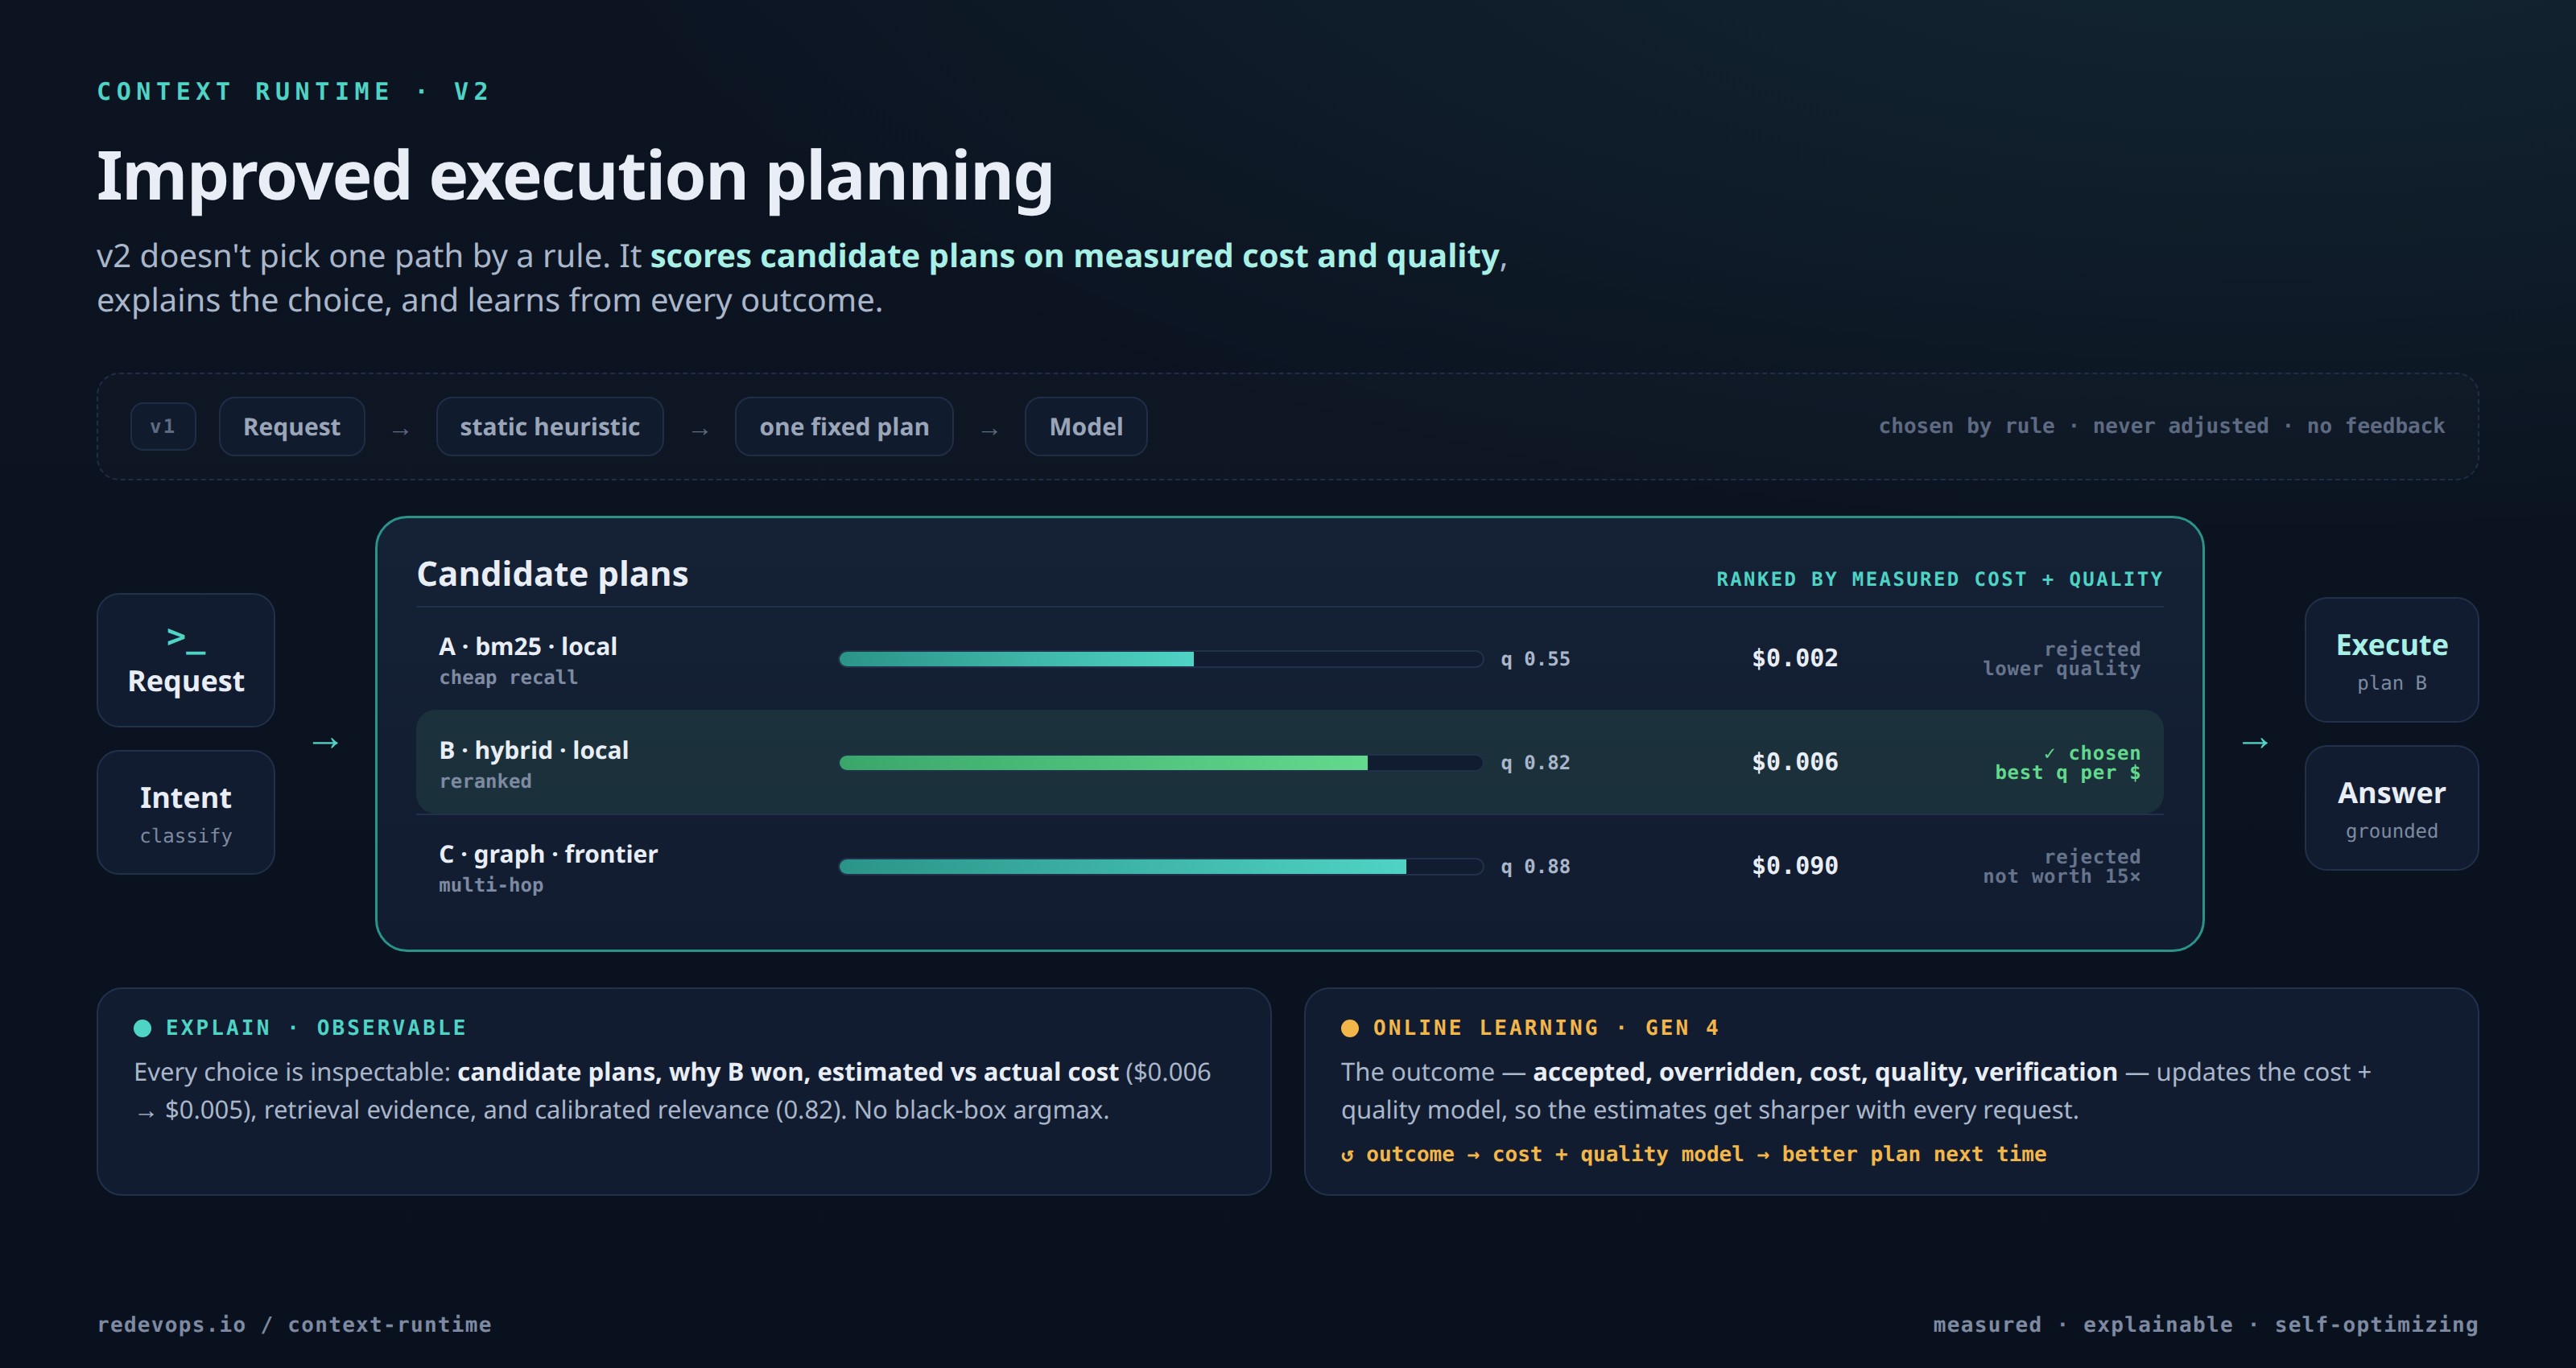
Applications describe intent. The runtime determines the initial execution strategy. Over time, it continuously improves those decisions using measured execution outcomes. Cost-based planning gets you the first execution; learning gets you the thousandth.
Since v1.1, the reference implementation has grown a body of runnable, measured evidence for that learning loop — including a result we did not expect on the messiest, most realistic input of all: a single user's mix of very different data. Those results are in the Evidence section, and every number is produced by an example, not asserted. And crucially, the runtime is inspectable: an EXPLAIN surfaces every decision it makes — which is what turns "the runtime decides for you" from a risk into something a team will actually ship.
The Problem
Current AI systems are built around static pipelines — User → Prompt → RAG → Model → Answer. Every serious application eventually extends that pipeline: hybrid search, BM25, GraphRAG, conversation memory, prompt caching, summarization, agent routing, verification, model selection, policy enforcement.
Every feature introduces another branch of application logic. As systems become more capable, developers spend less time building products and more time maintaining context pipelines. This is rapidly becoming the dominant engineering cost of production AI.
The static pipeline — and the sprawl it grows. Every capability bolted onto User → Prompt → RAG → Model → Answer (hybrid search, BM25, GraphRAG, conversation memory, prompt caching, summarization, agent routing, verification, model selection, policy enforcement) becomes another branch of application code — the maintenance burden, not the product.
Existing Approaches Solve Different Problems
Today's leading AI companies optimize different parts of the stack:
- Classical RAG reduces inference cost by retrieving less information.
- DeepSeek reduces attention cost by making models process long context more efficiently.
- Anthropic manages the lifecycle of context across long-running conversations and agents.
- OpenAI increasingly distributes reasoning across orchestration, planning and verification.
These approaches are complementary. None provides a unified runtime responsible for deciding how context should flow through an AI system — and learning to route it better over time.
Our Thesis
Context management should become an operating-system service rather than application code. Applications should no longer decide retrieval strategy, chunk size, reranking, prompt assembly, model routing, verification, compression or caching.
Applications should express intent. The runtime should determine the optimal execution plan — and refine that plan as it observes what actually works.
This is exactly what modern database query planners did for relational databases. Developers write SQL; the database determines how to execute it. Context Runtime applies the same principle to AI — and, like adaptive query optimizers, it uses execution feedback and statistics to get better with use.
The same abstraction databases have had since 1979. You write intent; the planner decides execution.
| Relational database | AI system | |
|---|---|---|
| SQL | ≈ | Goal |
| Query planner | ≈ | Context Runtime |
| Execution plan | ≈ | Execution graph |
| Result | ≈ | Verified result |
The Context Runtime
Instead of manually assembling prompts, applications submit goals. The runtime evaluates multiple strategies while respecting application constraints — latency, cost, security, token budget, verification requirements and provider capabilities. Only then does execution begin.
And execution is not the end of the loop. Each run produces a measured outcome — a reward — that updates the runtime's cost model and strategy selection, so the next plan for a similar intent is better than the last.
Context Runtime — plan, execute, learn.
           Goal  (the application's intent)
             │
      Intent analysis
             │
      Candidate plans  (several strategies)
             │
      Cost optimization  ── CONSTRAINTS ──────────────
      (score plans          • latency   • token budget
       vs constraints)      • cost      • verification
             │              • security  • provider capabilities
      Execution graph
             │
      Execution  (pluggable scheduler)
             │
         Reward  (measured outcome)
             │
      Bandit learning  +  cost-model update
             │
      Updated planner ──▶ (better next plan)
Intent in, a cost-optimized execution graph out — verified before a single token is generated, and improved after every run.
Architecture
Context Runtime separates planning from execution. The planner produces an Execution Graph; a pluggable scheduler executes that graph. Foundation models and retrieval systems become interchangeable plugins, verification becomes a runtime policy — and the application remains unchanged.
The runtime emits a backend-independent Execution Graph. The reference implementation includes an in-process scheduler and defines interfaces for distributed execution engines such as Dagster, Ray and Spark — so the same plan can run locally today and on distributed backends tomorrow without changing the planner or the application.
Data lives behind the same seam. A store is a plugin: the reference implementation ships an in-process store, a DuckDB backend (a persistent, embedded full-text index — one file per source or per user's local data) and a Postgres backend (tsvector), all interchangeable under the planner. Where information lives becomes a runtime decision, not application code.
Architecture — planning separated from execution.
  Application  (expresses intent — submits a Goal · stays unchanged)
       │
  ┌────────────── CONTEXT RUNTIME · THE PLANNER ──────────────┐
  │  Provider-independent      Execution graph + verification  │
  │  cost-based planning       (verification = a runtime policy)│
  │  + outcome-driven learning                                 │
  └────────────────────────────────────────────────────────────┘
       │
  EXECUTION BACKENDS & INTERCHANGEABLE PLUGINS
  [ in-process ]  [ Dagster ]  [ Ray ]  [ Spark ]   [ Models ]  [ Retrieval ]  [ Stores ]
Plan once, run anywhere: the planner is provider-independent; models, retrieval, stores and execution engines are swappable underneath it.
Retrieval as a first-class, routable capability
Retrieval is not a single fixed strategy but a set of runtime primitives the planner selects and cost-models per request:
- Sparse (BM25) — IDF-weighted lexical matching for exact, rare terms.
- Dense (semantic embeddings) — bridges synonyms and morphology across languages.
- Hybrid — BM25 ⊕ dense fused by Reciprocal-Rank Fusion.
- Graph / multi-hop — Personalized-PageRank over a passage graph for connective questions.
- Agent memory as three routable indices — conversation memory is not one store but three: recency (what was just said), semantic (what was decided), and entity (who/what a turn is about). The runtime learns which index a given turn needs instead of reading all three every time.
- Heterogeneous, multi-source retrieval — when a corpus is a mix of very different data (financial records, medical records, personal notes), the runtime shards by source, fans out in parallel, and learns which domain a question belongs to — routing to it rather than fusing everything. This is the case general-purpose RAG handles worst and the case real users actually have.
- Learned method routing — across all of the above, the runtime learns which method (and pool size, reranking, thresholds) wins for each intent, from measured outcomes.
Observability — EXPLAIN for context
A query planner is trusted only because you can ask it why. A database's EXPLAIN ANALYZE shows every node of the plan, its estimated and actual cost, and the rows it touched. A runtime that plans retrieval on your behalf owes developers the same thing — because when an answer is wrong, there is otherwise no way to tell whether the retriever fetched the wrong passage, the ranking cut the relevant one, or the context was simply too weak to answer. Without that, no team ships it to production.
So the runtime exposes an EXPLAIN of its own — read-only, so inspecting never perturbs what it has learned:
- The decision. Every retrieval strategy the planner could have chosen, ranked by its learned value, each annotated with a quality/cost decomposition and why it won or lost — "highest learned reward", "under-explored", or "quality-routed". The choice stops being a black-box argmax.
- The retrieval trace. Every method side by side, each candidate passage carrying a calibrated
P(relevant)rather than a scale-free raw score. This makes the failure mode the hardest to catch — a relevant passage cut by ranking — literally visible: a lexical hit can score3.07on raw BM25 yet calibrate toP(relevant) = 0.00, and the trace flags it as high raw score, low calibrated relevance — exactly the trap a raw-score ranking falls for. - Served, abstained, and why. What was actually served — or an honest abstention when the best passage is too weak to answer — together with the reward provenance: the runtime learns primarily from the native implicit signal (a kept vs. regenerated answer), and uses an LLM judge only as a cold-start bootstrap, never as the arbiter.
The same EXPLAIN is available as plaintext, as a read-only API endpoint, and as a live panel — so it renders identically in a terminal, a test, and the product.
You submit a goal; the runtime plans, retrieves, and can show its work — every candidate strategy, every passage's calibrated relevance, and the one decision it served.
Quality-aware routing
Provider-agnostic is not the same as provider-equal. Two models — or two retrievers — can cost the same and fail differently: they hallucinate in different places; they find different wrong answers. A planner that routes on price and latency alone cannot see that. So the runtime tracks quality apart from cost, per intent, for every choice — and because the choice key is arbitrary (a retrieval method or a model/provider), the same mechanism learns Claude-versus-Gemini quality per task type, not merely their price. A genuinely better option is then preferred at equal cost, instead of being hidden behind a single cost-blended number. It is opt-in and explores before it exploits, so it never locks onto an option it has not yet measured.
Evidence — Measured Results
The loop above is not aspirational. The reference implementation ships runnable benchmarks; every figure below is produced by an example program, not asserted.
Heterogeneous data — the case real users actually have. A person's local files are a mix of domains, and indexed as one flat store they collide: discharge (hospital vs. debt), statement (patient vs. financial), balance (fluid vs. sheet), chronic, liability. Measured on real financial 10-K filings plus a medical corpus:
| Retrieval strategy | Answer recalled | Cross-domain noise (top-5) |
|---|---|---|
| Flat mixed index | yes | 2.5 wrong-domain docs / query |
| Sharded + rank fusion | yes | 2.9 — fusion alone makes it worse |
| Sharded + learned routing | yes | 0.0 |
The surprising part: the correct answer is recalled in every case — this is not a "the model can't find it" problem. The failure is context pollution — a medical question drags financial pages into the window, and naïve fusion adds more. The runtime learns which domain each question belongs to and routes to it, driving cross-domain noise to zero while preserving recall, in both directions. This is the self-optimizing loop applied to a single user's own heterogeneous data — an edge no fixed pipeline has.
Agent memory that learns what to recall. With conversation memory exposed as three indices, the runtime learns — per question type — which one to read. Against a baseline that always reads all three, the learned policy improves reward (recall value minus read-cost) by +2.9, discovering on its own that follow-ups want recency, factual questions want semantic recall, and entity questions want the entity index.
The learning generalizes. Eleven reference applications each expose one context decision and one measured outcome; on every one, the learned policy beats a fixed full-context baseline — the same plan-execute-learn loop, eleven different domains.
A public, no-login demo runs this live: point it at a corpus and watch the runtime route and improve in real time.
Why This Matters
Today's AI applications are tightly coupled to providers and frameworks. Tomorrow's applications will depend on infrastructure that automatically determines:
- what information matters,
- where it lives,
- when it should be retrieved,
- how it should be compressed,
- who should process it,
- how it should be verified,
- and how to do all of the above better over time.
Context Runtime becomes that infrastructure layer.
Open Source First
The project begins as an AGPL-licensed reference implementation. Its purpose is to validate the architecture and establish an open specification for context management. The initial implementation focuses on:
- provider-independent planning,
- cost-based optimization,
- outcome-driven (self-optimizing) planning,
- execution graph generation,
- retrieval optimization (sparse · dense · hybrid · graph · agent-memory · heterogeneous · learned routing),
- quality-aware routing (learned quality tracked apart from cost, per intent, over arms or providers),
- pluggable stores (in-process · DuckDB · Postgres),
- verification,
- observability — EXPLAIN: the plan's ranked decision, per-passage calibrated relevance, served/abstain, and reward provenance.
The goal is not another agent framework. The goal is defining a new infrastructure abstraction. Multiple implementations of that abstraction are possible: Python and Go reference implementations exist today, at feature parity — the same planner, cost model, learning loop and retrieval seams in both, which is the strongest evidence that this is an abstraction, not a library.
Enterprise Vision
As AI workloads become larger and increasingly distributed, context planning itself becomes a distributed-systems problem. The long-term roadmap covers distributed planning and execution across Kubernetes, Dagster, Spark, Ray and future execution backends. This enables:
- multi-node context planning,
- high availability,
- enterprise policy enforcement,
- distributed plan caching,
- execution tracing,
- large-scale optimization,
- multi-tenant deployments.
The planner remains provider-independent while execution engines continue to evolve independently.
Market Opportunity
Every production AI system already performs context planning. Most simply do it manually. The industry has standardized foundation models. It has standardized tool calling. It has standardized retrieval. It has not standardized context optimization.
That missing layer represents an opportunity to define a new category of AI infrastructure.
Vision
Compilers removed the need to write assembly. Operating systems removed the need to manage hardware directly. Database query planners removed the need to handcraft execution strategies — and adaptive optimizers later removed the need to hand-tune them as data changed.
Context Runtime brings the same arc to AI. Applications describe intent. The runtime determines the optimal execution plan, and learns from every execution. Everything else becomes implementation.
Context Runtime is not another AI framework. It is the infrastructure layer that makes AI systems simpler, cheaper, more reliable, provider-independent — and self-improving.